4 min read
AI Coding Agents: From Writing Prompts to Designing Systems
This article is part of a series on AI coding agents "XXX engineering" terms. Its thesis: each new term (prompt, context, harness, loop, graph) adds...
8 min read
Emmanuel Sciara
:
Updated on October 29, 2026
This article is part of a series on AI coding agents' "XXX engineering" terms . Its thesis: each new term (prompt, context, harness, loop, graph) adds a ring around the last one instead of replacing it, and each article asks where the human sits. Find the other articles in the series:
“After Loop Engineering: Is Graph Engineering the Next Ring?” (this article)
“Harness Engineering, or Agent = Model + Harness” [coming soon, working title]
“Loop Engineering, or Sit on the Loop, Not in It” [coming soon, working title]

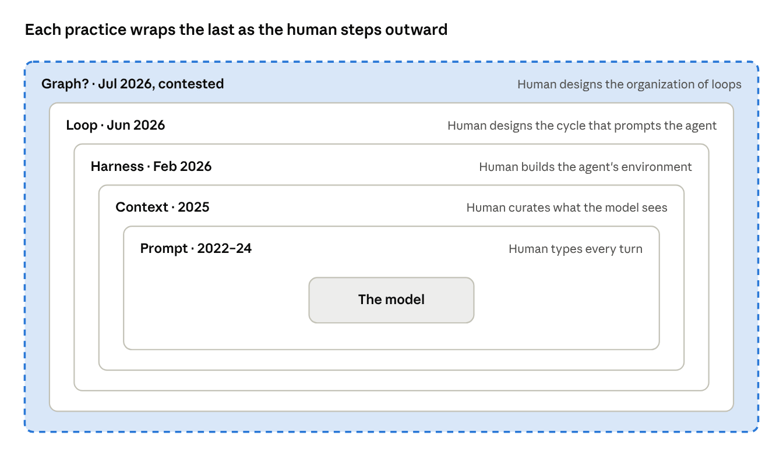
In the first article to this series, we introduced the diagram above with a ring dumbed "Graph? (July 2026, contested)". This article argues that question mark openly: is graph engineering the next ring around the loop, or did the ladder stop at loops... for now?
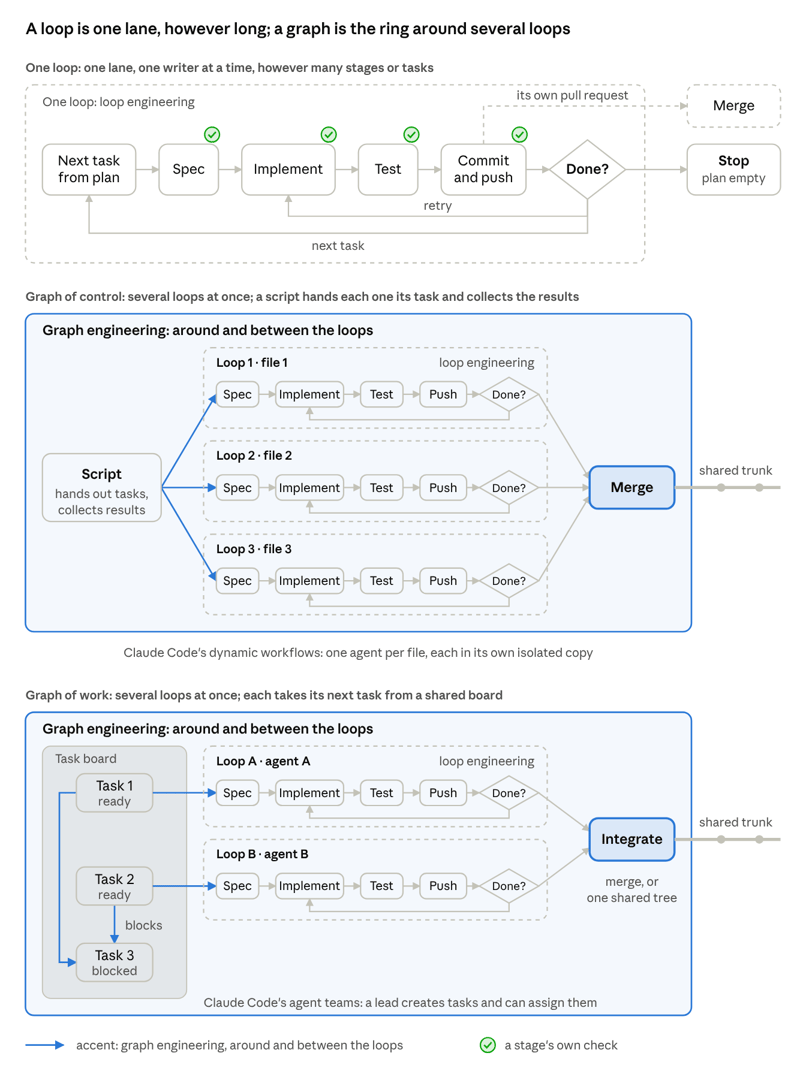
A loop keeps one line of work going until its stop condition holds
Each turn's result decides the next turn, and no human prompts in between. One turn can chain several stages: at Mergify, Rémy Duthu gives each issue one goal covering plan, spec, build, test and push, and reviews the result once it is pushed.
A loop can also work down a list, one task per turn, as Geoffrey Huntley's Ralph loop does with its plan file, fix_plan.md. Each stage can have its own check; the loop ends on one done-condition.
A graph engineers what happens between loops
That includes:
Which loop runs when;
Which waits for which;
How results pass from one to the next;
How their changes merge.
A loop that is the only writer can merge its own pull request, as OpenAI's Codex agents do; once several loops write to the same branch, merging becomes integration of others' work, which, for instance, Cursor hands to a separate merge agent.
The checks, the retries and the stop rule inside each loop remain loop engineering. To tell loop and graph engineering apart, count the writers:
One line of work writing at a time per branch, however many stages or sequential tasks, is a loop;
Several writing to the same branch at once, so that their changes must be integrated, is the next level (graph), because someone must then decide what runs in parallel, what waits for what and how the changes merge. Read-only helpers, such as a reviewer subagent or a goal evaluator, don't count.
Two recent preprints define the graph by its structure instead of counting workers: in a literature review, Yuyuan Feng and 34 co-authors build it from explicit graphs of tasks, agents and system states, and Sandeco Macedo's definition admits a chain of calls to a single model.
In our approach, a structure with one writer stays a loop, because one check still decides the outcome.
Others place parallel agents as being part of a loop:
Addy Osmani (now at Anthropic, formerly Google Cloud AI) lists worktrees for parallel agents among a loop's parts,
Anthropic's guide to loops composes parallel workflows into proactive loops,
Peter Steinberger introduced a timer that dispatches work to parallel threads as "a simple loop" (X, June 11, 2026)
This article keeps "loop" for one line of work, because that is where the check lives.
Coding-agent tools ship two forms:
Graph of control
Each node is a task worked by its own agent, in one run or in a loop, and a script decides what runs next and passes results along.
In Claude Code's dynamic workflows, Claude writes that script and a runtime executes it: one agent per file across a 500-file migration, each working in its own isolated copy. Bringing the copies back together is left to the script or to an agent.
A script that only retries one task (keep fixing until the type check passes) is a loop written as code; it becomes a graph of control when it runs several writers and decides their order and how their changes come back together.
Graph of work
Each node is a task taken by its own agent or loop, and each edge says which task blocks which. Agents claim whatever is unblocked.
Beads, built by veteran engineer Steve Yegge (formerly at Amazon and Google), works this way. A list worked through one task at a time is not a graph of work: it is that loop's plan.
Claude Code's agent teams (experimental, off by default) are a hybrid with a lead agent:
The lead creates the tasks and can assign them;
Teammates claim the unassigned, unblocked ones;
All of them share one working tree and avoid conflicts by owning separate files.
e a Most products ship neither: a lead agent splits the work and spawns subagents (Codex, Cursor, Devin, Amp), which it coordinates himself.
Where a team designs the hierarchy itself (roles, hand-offs, a merge step), those parts between loops are graph engineering too. Otherwise a human coordinates by hand, as with GitHub Copilot's coding agent, where someone assigns every issue.
Each ring in this series added to the previous one when the later was good enough and the bottleneck moved outward. The same test applies here, in two halves:
Has the main bottleneck moved between loops?
Has the human's job moved to designing what happens there?
Graph is the next ring only if both answers are yes.
If most of a team's time still goes into getting one loop to finish reliably, a graph only arranges unreliable loops in a more elaborate order.
The evidence to support this, below, dates from June 2026 or later and comes from four kinds of sources:
coding-agent vendors describing their own products and use: Anthropic (Claude Code), Cursor and Cognition (the maker of Devin). They support that, at scale, the bottleneck and the human have moved between loops (Cursor, Cognition), that coordination left to a lead agent costs accuracy (Cognition), and what the two graph forms look like in shipped tools (Anthropic);
engineers describing their own practice: Mergify, a company that sells merge queues to engineering teams such as Mozilla, Uber and Red Hat. It supports that the bottleneck moves even in a small team running many agents, from writing code to reviewing it, at the end of each loop rather than between them;
surveys and telemetry: GitKraken, the maker of a Git client, polling 554 people from its own community; and Jellyfish, an engineering analytics platform reporting on its customers' data. They suggest that the bottleneck has not moved for most teams, since few run agents autonomously;
research: a preprint from Azalia Mirhoseini's group at Stanford, not yet peer-reviewed. It supports that coordination left to an agent's default subagents costs accuracy, and that coordination designed for the work can pay.
Most of these sources have a stake in what they report, and none is a controlled study of the trade.
yes, for teams at scale:
Cursor runs hundreds of coding agents at once; with the same task, models and time budget, its previous harness hit more than 70,000 merge conflicts before it was paused, and the new one fewer than a thousand.
Smaller teams hit limits around the agents: at Mergify, an engineer running at least ten sessions on a normal day (each in its own worktree and branch) found that the bottleneck moved from writing code to reviewing it, at the end of each loop rather than between them.
probably not for most teams:
In GitKraken's July survey of 554 developers and leaders, 28% work with AI mainly in autonomous mode, and 22% don't run agents at work.
Across more than 1,300 companies, Jellyfish counts a median of 0.6% of merged pull requests coming from autonomous agents.
Both measure how autonomously agents run, not how many write at once: five interactive sessions in separate worktrees would show up in neither.
yes, at scale, to what happens between loops:
Cursor's engineers designed what sits between their agents: planners that split the work, a merge agent that resolves conflicts for all the others, and their own version control.
For security scans across a whole repository, Cognition scripted a pipeline that runs one agent per batch of code and merges the results: a graph of control.
At Cursor, a person writes the spec, no one steps in during the run, and the code is reviewed afterwards. That already holds for one loop: at Mergify, an engineer reviews each pushed pull request himself. The spec and the review don't tell graph from loop.
not where teams take the defaults:
Yuzhen Mao and colleagues at Stanford found that Claude Code on Opus 5.5 solved about 72% of ten long DeepSWE tasks alone and 50% when told to use its subagents, at a higher cost per task. Three caveats:
the gap holds on one benchmark: on ten Terminal-Bench tasks, Claude Code lost under two points with its subagents (82% to 80%);
part of it measures a default: many failed runs hit the ten-minute idle limit that Claude Code applies to background work in non-interactive runs;
the authors have a stake: they propose the shared-queue design they test against Claude Code.
Cognition saw the same with Devin: "When the judgment is the deliverable, delegating it backfires." Coordination left to a lead agent's judgment costs accuracy.
Surveys suggest that most teams are not yet running enough loops to need coordinating them: their work still happens in one loop.
Teams that run many agents have hit limits in two places:
Between loops, in merging, where agents collide at Cursor's scale;
At the end of each loop, in review, as, for instance, at Mergify.
Only the first is graph engineering, and Cursor's engineers now design what happens between their agents. For teams at that scale, graph is a plausible next ring: their bottleneck has moved, and so has the human.
What they build depends on the form:
designed hierarchies at scale: Cursor's planners and workers, with merging handled between them;
graph of control where the work can be listed up front: Cognition's repository-wide scans, Claude Code's one agent per file;
graph of work only at the frontier: shipped in beads and Claude Code's agent teams (experimental), but apart from Yegge, no team has publicly reported running one in production since June. Anthropic itself sends work with many dependencies back to a single session or subagents, although dependencies are what a graph of work encodes.
In each case, teams added structure rather than removing it. Designed for the work, coordination can pay: the same Stanford study found that agents sharing one work queue and one context beat the single agent, at 88%.
Yegge plays another game altogether. He wrote in August that his first orchestrator, Gas Town, "fell apart at the seams with Opus 4.7": the new model kept tinkering with the orchestrator instead of doing the work. Its successor, Wheelhouse, runs more than 40 agents around the clock on top of beads, lands 120 to 150 commits at once and keeps more than 700 designed tasks queued for overnight work. It adds far more structure than Cursor: role agents, written rules, a merge queue. Wheelhouse shows where coordination can go at the far frontier, not where most teams are, and it is built for one application, not as a layer others can reuse.
The next ring may also arrive under another name. "Graph" meant four different things in the July debate, as Turing Post counted. Outside coding, declared graphs are common: LangGraph, Microsoft Agent Framework and Google ADK 2.0 model agent workflows as graphs, mostly for business processes. The coding-agent tools call their versions subagents, task lists, workflows, missions or teams. Whatever the name, the test stays the same: does coordination limit you more than any single loop does?
If graph engineering is the next ring, the human sits between the loops, designing what runs when and what blocks what.
Graph may stick, or the next buzzword may arrive before this series ends. When it does, don't ask what it's called. Ask where it puts the human.
Coming next in the series: how the environment became the lever [article to be published], and where the harness ends and the loop begins [article to be published].
Turing Post, "FOD#159: Is Graph Engineering Real?", July 20, 2026: the four meanings of "graph"
Steve Yegge, "The Shape of Things to Come, Part 1: The Continuous Thunderdome", yegge.ai, early August 2026; quoted by Simon Willison, August 4, 2026
gastownhall, beads README, GitHub, read October 10, 2026
Anthropic, "Orchestrate teams of Claude Code sessions", Claude Code docs
Anthropic, "Orchestrate subagents at scale with dynamic workflows", Claude Code docs
Cursor, multi-agent help page, undated
Wilson Lin (Cursor), "Agent swarms and the new model economics", July 20, 2026
Cognition, "Agentic MapReduce", July 1, 2026
Cognition, "Devin Fusion: Frontier Performance at 60% Lower Cost", June 29, 2026
Rémy Duthu (Mergify), "How Agents Work With Parallel Agents", June 8, 2026
GitKraken, "State of AI", July 2026
Jellyfish, "AI Engineering Trends", September 2026
Yuzhen Mao et al., "Decentralized Multi-Agent Systems with Shared Context", arXiv, June 9, 2026 (v3 October 4, 2026)
OpenAI, Codex subagents docs, undated
Microsoft Learn, "Assigning, tracking, and troubleshooting Copilot coding agent tasks", undated
Factory, Missions overview, undated
Sourcegraph Amp, "Modes & Models", undated
Google, "Why we built ADK 2.0", July 1, 2026
Microsoft, Agent Framework workflows docs (search snippet only)
Geoffrey Huntley, "Ralph Wiggum as a 'software engineer'", ghuntley.com, July 14, 2025
Ryan Lopopolo (OpenAI), "Harness engineering: leveraging Codex in an agent-first world", February 11, 2026
Addy Osmani, "Loop Engineering", addyosmani.com, June 7, 2026
Peter Steinberger, post on X, June 11, 2026
Delba de Oliveira and Michael Segner (Anthropic), "Loop engineering: Getting started with loops", June 30, 2026
LangChain, LangGraph product page, read October 19, 2026
Yuyuan Feng and 34 co-authors, "Graph Engineering in the Era of LLM Agents: From Individual Intelligence to System Intelligence", arXiv, August 21, 2026 (v2 August 26): a literature review
Sandeco Macedo, "What makes prompts a graph: necessary and sufficient conditions for prompt graph engineering", arXiv, July 30, 2026
Anthropic, "Run Claude Code programmatically", Claude Code docs, read October 21, 2026
4 min read
This article is part of a series on AI coding agents "XXX engineering" terms. Its thesis: each new term (prompt, context, harness, loop, graph) adds...
This article is part of a series on AI coding agents' "XXX engineering" terms. Its thesis: each new term (prompt, context, harness, loop, graph) adds...